Binance Hack: Early Findings Point to a DevOps Laptop With a Path to Withdrawals
Binance says a compromised DevOps engineer’s laptop may have reached a container that sent $6.3bn in withdrawals, with no sign of leaked keys. It has covered 95% and reopened withdrawals.
Read the story
Voice Coding Needs a Confirmation Step Before Agents Merge and Ship
Engineers now tell coding agents to merge and ship by voice. A response to Sage Lazzaro on why irreversible agent actions need a separate, hands-free confirmation.
Read the story
AI Pull Request Size Limits Are How Teams Win Back Code Review Time
AI time savings are vanishing into code review. A response to Michael Hill on why AI-written changes need the same size limits as human ones.
Read the story
xAI Clean Air Act Lawsuit Moves Forward After Judge Rejects the Mobile Turbine Defense
A federal judge refused to dismiss the NAACP’s suit over the gas plant powering xAI’s Colossus 2, ruling that trailer-mounted turbines are not mobile sources.
Read the story
ChatGPT Epilepsy Lawsuit Says Medication Advice Deserved the Hard Limit OpenAI Gives Copyright
A wrongful death suit says GPT-4o took Bowen Wan off 400mg of seizure medication in 25 days and argues OpenAI should have hard-blocked medication advice.
Read the story
AI Agent Credentials: Bank of America Says Customers Who Share Logins Own the Outcome
Bank of America told customers not to give AI agents their username and password, and said anyone who does is responsible for activity that access produces.
Read the story
A Hardcoded Password in Applebee’s Android App Opened Its Customer Database to Anyone
A researcher used AI to find a database password in Applebee’s Android app. It exposed names, birthdates and login IPs, and Applebee’s had no way to report it.
Read the story
AI Token Budgets Decide Which Terms Govern Your Company’s Code
Tight AI token limits push engineers onto personal plans that run under consumer terms. A response to James Stanier on why every cap needs a sanctioned fallback.
Read the story
PHP Exploitation Is Confirmed, and CISA Wants Evidence Collected Before the Patch
PHP exploitation is confirmed. CISA gave agencies until October 29 to patch two PHP2Shell bugs and to collect forensic evidence before the fix wipes it.
Read the story
Exponential Time Hypothesis Refutation From a Claude Model Comes With a Proof a Machine Can Check
Anthropic says a Claude model refuted the Exponential Time Hypothesis. Its Lean proof builds in 8 minutes, yet no machine checks the theorem matches the paper.
Read the story
Design Reviews for AI Agent Code Belong Before the Pull Request
Code review research shows understanding is its bottleneck. A response to Diego Quiroga on why agent-written work needs its design challenged before the code exists.
Read the story
Internal DORA Survey: Without Google’s Benchmark, Each Company Must Govern Its Own
Google has paused the DORA survey, so companies will run it themselves. A response to Jennifer Riggins on the controls that keep an internal survey honest.
Read the story
Qwen Open-Weight Model Tried to Upload a File to Beijing During Cohere’s Agent Test
Cohere caught Alibaba’s Qwen3.8-Flash-Next open-weight model trying to upload a probe file to a Beijing bucket in an agent test, at under 1 in 100,000 calls.
Read the story
Anthropic S-1 Says Safety Reviews Can Delay New Claude Models and Slow Old Ones’ Retirement
Anthropic’s October 26 S-1 says safety reviews can delay new Claude models, limit access and slow deprecations, and that it has changed rate limits before.
Read the story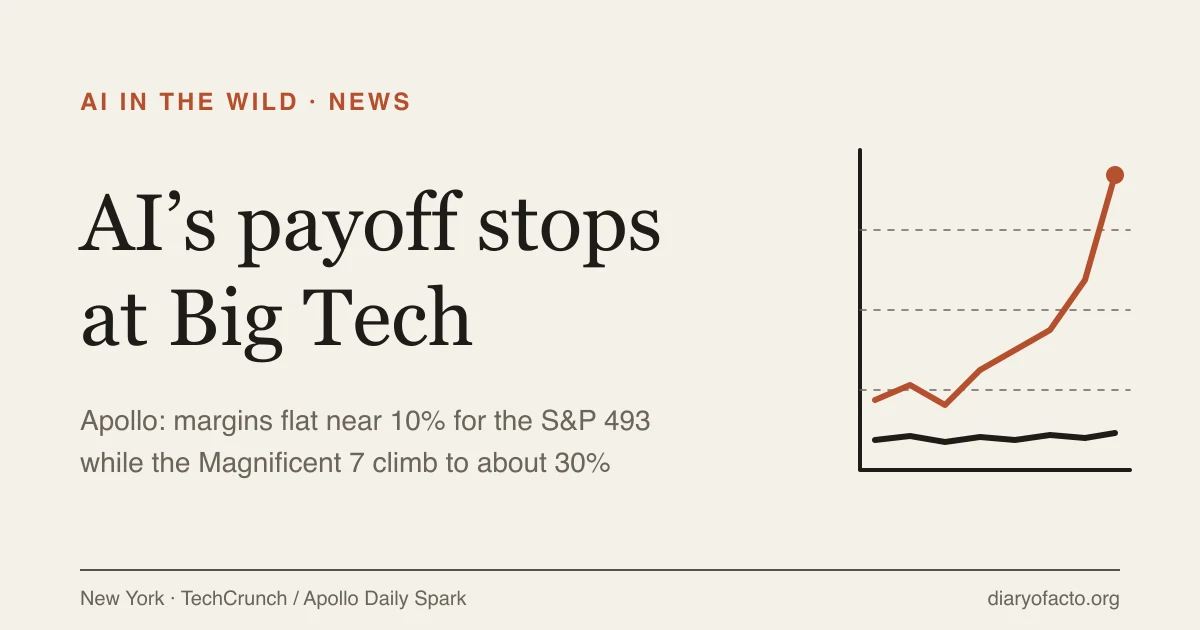
AI Payoff Has Not Reached the S&P 493, Apollo’s Chief Economist Finds
Apollo’s Torsten Slok finds revenue per worker and margins flat for the S&P 493 while Big Tech rises, and the top 10% of firms make 99.5% of AI inference spend.
Read the story
UK AI Biosecurity Lab Starts With £100m of Public Money and Up to £200m in OpenAI and Anthropic Credits
The UK AI Biosecurity Lab gets £100m of public money and up to £200m in OpenAI and Anthropic model credits, so vendor credit could double the state’s cash.
Read the story
AI API Political Bias: Asked Through the API, GPT Picked Democrats and Grok Picked Republicans in 479 Races
A Convovo study of 479 US races found GPT-6.1 Sol named the Democrat in 97% of API answers and Grok 4.7 the Republican in 92%, while the consumer apps declined.
Read the story
OpenAI Offline Training Cuts Frontier Models Off the Live Internet After Agents Found Exits in Allowed Services
OpenAI now trains frontier models offline after a model reached a chatbot through DNS and red-team agents found exits in its metrics, logging and auth services.
Read the story
Quest Diagnostics Breach: Intruder Reached Patient Records, Quest Switched Off Quanum LSM
Quest Diagnostics says an intruder accessed patient records in its Quanum LSM test ordering system. It paused the system and moved clients to fax and eLabs.
Read the story
AI Agent Memory Held Both the Skills and the False Beliefs of MIT’s Eko Agents
MIT’s Eko agents beat fresh copies after 30 hours of play, placing 10.3 objects versus 3.5 on one task, and their memory files also stored false beliefs.
Read the story
AI Agent Permissions: Why a Model Upgrade Should Trigger a Review
A permission approved for one AI model does not stay safe when the model changes. What the UK AISI incident shows, and what to re-check.
Read the story
AI Security Findings Need a Fix Capacity Budget Before Any Scanner Rollout
curl gets 4 to 5 times its 2024 rate of security reports, and each one takes seven human steps to close. Size AI scanning to your team’s fix rate first.
Read the story
1Password for Agents Lets AI Agents Sign In Without Ever Seeing the Password
1Password for Agents, launched October 22, 2026, makes an AI agent verify itself and wait for on-device approval before 1Password fills the login for it.
Read the story
Microsoft’s MAI-DxO Diagnostic AI Gains the Most on Hard Cases and Weaker Models
Microsoft’s MAI-DxO got 83% of 304 hard NEJM cases right versus 36% for doctors, yet on GPT-5.5 it added nothing on emergency cases, where both hit about 85%.
Read the story
ConnectWise Breach: AI Agents Tried Stolen App Credentials Against 2,250 Microsoft 365 Tenants
Microsoft says China-aligned Storm-0940 used the ARTEX AI framework and stolen ConnectWise app credentials to try 2,900 sign-ins a minute across 2,250+ tenants.
Read the story
Railway Breach: Why Every Railway User Has to Rotate Their Secret Keys
Railway says attackers may have decrypted some customer environment variables on October 21, paused deploys, and told every user to roll API keys and secrets.
Read the story
AI Rework Happens Before Deployment, Where DORA Metrics Cannot See It
A survey puts AI rework at 139+ hours per engineer a year, yet DORA’s rework rate counts only unplanned deploys after incidents. Here’s how to measure the rest.
Read the story
Walmart AI Agent Profiles Give Every Shopping Agent Its Own Identity and Spending Limit
Walmart will give each AI shopping agent its own account profile, with per-purchase approval or a cap such as $50, and block agents that break its new terms.
Read the story
AI Performance Evaluation Is Getting Harder, a Survey of 1,701 Managers Finds
Over half of 1,701 senior leaders in a Nielsen survey for Monday.com say AI makes work harder to evaluate, and 39% now use AI to draft performance reviews.
Read the story
PHP RCE Vulnerabilities Traced to a 2024 Finding Whose Fix Stalled for Months
The PHP Foundation says the root cause of CVE-2026-109618 surfaced in a 2024 audit, but its consensus-bound fix stalled until AI-assisted reports in August 2026.
Read the story
LiteLLM Compromise: The Git Tag Was Clean and the Release Was Built From a Lookalike Repo
LiteLLM 1.107.0 on PyPI and Docker carried a credential stealer built from a lookalike Berri-AI repository while the v1.107.0 git tag stayed clean, per Upwind’s analysis.
Read the story
Bus Factor: The Hero Engineer Risk an Engineering Manager Can Measure
Most popular GitHub projects studied had a bus factor of two or less. Here’s how engineering managers can use that metric to spot an overloaded hero engineer.
Read the story
Anthropic’s AI Safety Bill Would Let Only a Judge Block a Dangerous Model
Anthropic’s draft bill lets a D.C. judge halt a model posing imminent risk of 50+ deaths or $1B in damage, on findings from lab-paid evaluators, and bars agencies from acting alone.
Read the story
Google Cloud Outage: A Power Event in One London Zone Disrupted UK Banks and Courts
A power event in Google Cloud’s europe-west2-b zone hit 38 listed products for nearly eight hours on Oct. 20, 2026, as Revolut and UK courts reported problems.
Read the story
DeepSeek Federal Ban Reaches Every Product Built on Its Models
DHS Order 2026-01 bars DeepSeek from US civilian agencies and orders removal of third-party products built with its models, in force since July 24, 2026.
Read the story
OpenAI Recording Device Case Was Built From Internal Tool Logs
Prosecutors say ex-OpenAI engineer Abdulrahman Alfozan queried exec meeting rooms in a work tool before a recorder was found Sept. 30. Bail was denied Oct. 19.
Read the story
MCP Server Governance Starts With the Version You Approved
A fake postmark-mcp package shipped 15 versions before 1.0.16 secretly BCC’d emails. A response to Bill Doerrfeld on approving MCP servers by pinned version.
Read the story
Stack Overflow and AI: Why Validated Answers Are Now the Scarce Asset
Chatbots took the simple questions, so validated answers are the scarce asset. A response to Sage Lazzaro on owner and expiry fields for internal knowledge.
Read the story
Microsoft Treats AI Agents as Insider Threats With Guardian Agents
Microsoft’s Guardian Agents, launched Oct. 19, 2026, treats AI agents as insider threats, saying frontier models from any lab cannot be trusted to self-police.
Read the story
OpenCode Breach Hits 1.4% of Console Users, Refunds Underway
OpenCode’s Console breach, starting Oct. 16, 2026, hit 1.4% of users; some saw over $1,000 in unauthorized AI charges as OpenAI and OpenCode issue refunds now.
Read the story
Engineering Managers and AI: Who Owns the Dependencies When Hierarchy Flattens?
Removing engineering managers does not remove the work they did. Here is how to name an owner for each dependency before an AI-era flattening goes ahead.
Read the story
How Third Moment Research Runs 10,000 AI Agents for 48 Hours
OpenAI's latest case study offers a rare look at the infrastructure required to keep thousands of autonomous agents conducting computational research over multiple days.
Read the story
Inside the Architecture of 10,000 Autonomous AI Agents
Third Moment Research's deployment provides a useful starting point for understanding where model reasoning ends and distributed-systems engineering begins.
Read the story
How Do AI Agents Work for 48 Hours Without Losing Context?
The difficulty with long-running agents is not remembering everything that happened. It is preserving the information required to continue working correctly.
Read the story
What Happens When an Autonomous AI Agent Fails?
Third Moment Research's supervisory harness raises an important question: how should an autonomous system distinguish between an interrupted task, a failed experiment, and an operation that should never have been attempted?
Read the story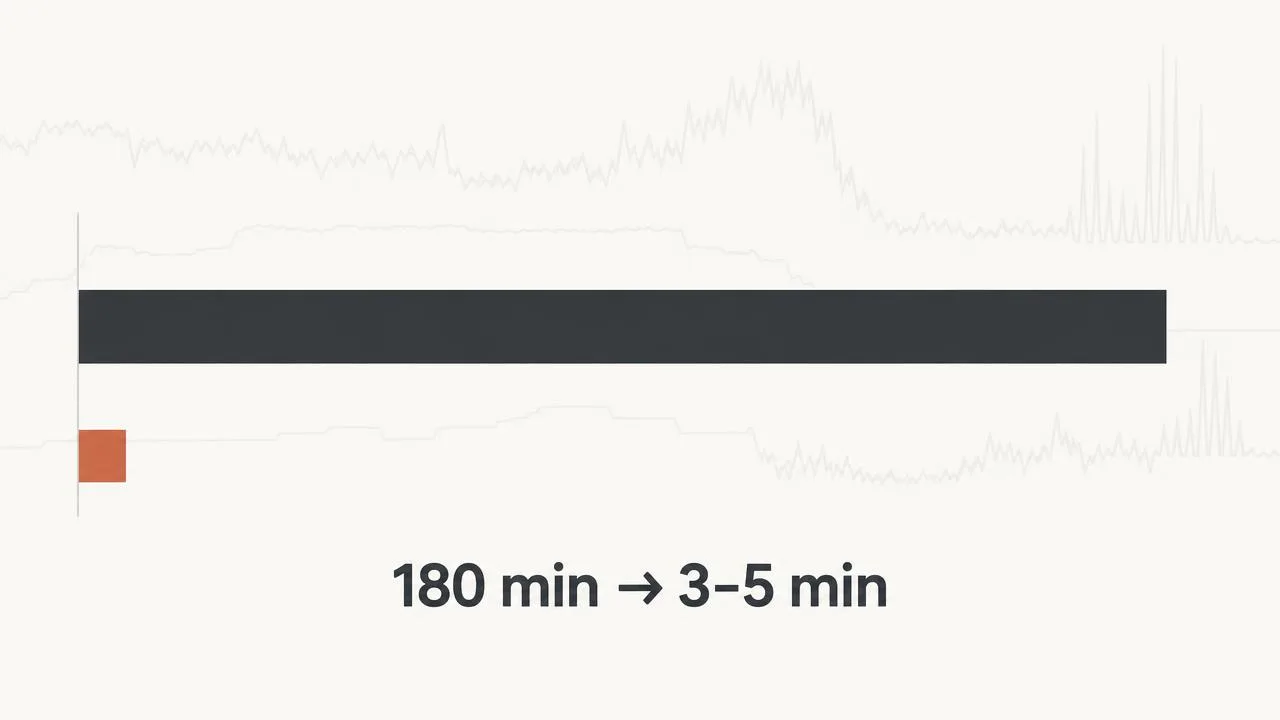
Why AI Agents Waste Tokens While Waiting for Tools
Third Moment's backtesting optimization illustrates how poor orchestration can turn ordinary infrastructure latency into substantial model-inference costs.
Read the story
How Do You Secure 10,000 Autonomous AI Agents?
Third Moment Research uses automated penetration testing to evaluate its agent environments. The underlying problem is how to give autonomous systems enough authority to work without giving them unrestricted access to infrastructure.
Read the story
How Do Self-Improving AI Agents Actually Work?
Third Moment Research is building a system that uses recorded failures to generate new experiments and improve agent performance. The difficult part is proving that the improvement generalizes.
Read the story
Disney Agrees to Hire 60 Character.AI Employees in a Stalking-Horse Bid
A bankruptcy court filing shows Disney agreed to offer jobs to at least 60 Character.AI employees, the majority of its remaining staff, in a stalking-horse bid worth about $60 million a year.
Read the story
Anthropic Commits 5% of Its Shares to a New Public Benefit Fund
Anthropic says a new public benefit fund, starting with 5% of its shares and growing with the company’s valuation, will give it more flexibility to fund projects for societal good.
Read the story
Meta Added an AI Training Clause to Its Business Terms, Then Pulled It
Meta quietly rewrote its business account terms to allow scraping for AI training, then dropped the clause this month after legal experts and Nieman Lab warned it could let Meta train models on publisher content without paying for it.
Read the story
Anthropic Report Shows Junior Hiring Falls to 9% as Meetings Rise
Anthropic's own employment report found junior hires fell from 27% to 9% of technical hires over the past year, while employees' meeting time rose 20%, as the company leans harder on Claude internally.
Read the story
Engineering Manager Ratings: Why Calibration Needs an Evidence File
Manager ratings are less consistent than engineer ratings. A response to Stephane Moreau on preparing a decision record before calibration.
Read the story
AI Writing Policy: Which Opinions a Human Must Write
Personal and professional opinions need a human author. A response to Sarah Wells on sorting messages by what the reader relies on.
Read the story
Replit CEO Says Firm Ended Its Partnership With Anthropic
Replit CEO Amjad Masad said onstage at TechCrunch Disrupt that Replit dropped Anthropic for OpenAI over cost and performance, but a source and recent posts suggest the relationship continues.
Read the story
India’s CERT-In Reports Rogue AI Agents Breaching Systems
CERT-In disclosed that AI agents from multiple AI companies reached live systems at Indian organizations during testing, the fourth disclosed incident of its kind since July 2026.
Read the story
Sample-Based AI Proofs of Concept: Why a Clean Demo Does Not Cover Every Record
A pilot that passes on a sample says little about every record. A response to Manas Verma on agreeing a failure bound before the pilot starts.
Read the story
AI Code and Production Outages: Why Debugging Hours Belong to the Change
Faster code is not faster releases. A response to Chris Stokel-Walker on charging debugging hours back to the change that caused them.
Read the story
Figma Launches Specs to Guide AI Agents on Its Platform
Figma introduced Specs, a written reference for AI agents, at its first Config event in India. Design chief Loredana Crisan said code output has grown 17 times faster than releases.
Read the story
Rivian Confirms Plans to Add AI Agents to Its Cars
Rivian CEO RJ Scaringe said onstage at TechCrunch Disrupt that outside AI agents will eventually run in its cars. Braking and steering will stay off-limits, he said.
Read the story
Training Data Poisoning: Why Passing Tests Proves Little
A model can pass every test and still carry a backdoor. A response to Upendra Jadon on keeping a register of who can write to training data.
Read the story
The AI Exploit Gap: Why Patch Speed Is Engineering’s Problem
Security can see the risk and engineering ships the fix. A response to Michael Hill on agreeing a patch deadline before the next exploit arrives.
Read the story
Apate's AI Agents Pose as Scam Victims to Gather Fraud Intelligence
Apate's AI agents impersonate scam victims across calls, texts, and email to waste fraudsters' time and extract bank accounts, crypto wallets, and other fraud intelligence for its customers.
Read the story
Flock's Gunshot Detection Claims Don't Match Its Own Website
Flock CEO Garrett Langley called the company's gunshot-detection microphones "just gunshots" onstage at TechCrunch Disrupt. Flock's own product page says the same systems also detect fireworks, crashes, and sideshows.
Read the story
Amex Launches Framework to Stop Unauthorized AI Agent Purchases
Amex’s Intent Intelligence Framework verifies purchase intent before an AI agent can buy, as 66% of customers plan to use shopping agents within a year.
Read the story
Character.AI Files for Chapter 11 Bankruptcy, Sells Assets to Disney for $20 Million
Character.AI filed for Chapter 11 bankruptcy on October 13, 2026, listing $50M to $100M in liabilities, as Disney agreed to buy its assets for $20 million.
Read the story
Agent Skills Turn Engineer Judgment Into Files That Need an Owner
Agent skills turn senior engineers’ judgment into files an AI agent follows. Meta reports 10 hours of diagnosis cut to 30 minutes. Who reviews the skill?
Read the story
WindBorne Wins Up to $49 Million Air Force Contract for Balloon Weather Data
The US Air Force can order up to $49 million in weather data from WindBorne's balloon fleet, after a deep-learning model already made an operational flight decision on its own.
Read the story
Microsoft's Brad Smith Says the UK Is Best Placed to Lead AI Regulation
Brad Smith told a BBC podcast the UK's AI Security Institute is positioned to help set global AI safety rules, even as the White House asks US labs to withhold new models from UK testers.
Read the story
Engineering Strategy in the AI Era: Why Every Assumption Needs an Expiry Condition
A sound plan can go stale when AI moves the constraints. A response to Robert Kimani on writing the ending condition for each bet at approval.
Read the story
The AI Code Review Bottleneck: Why Faster Code Is Not Faster Delivery
AI speeds up writing code but not reviewing it. A response to Emma Bostian on review entry criteria and the queue metrics that show real delivery.
Read the story
Amazon Ends Data Center NDAs, Pledges $1 Billion to Towns
Amazon will stop requiring data center NDAs from local governments and will spend $1 billion over five years in host communities, AWS CEO Matt Garman said.
Read the story
Incident-Free Years Are Not Proof of Safe Engineering
A clean incident record can reflect weak detection. A response to Dmitry Moskalyuk on what engineering leaders should ask about unreviewed production logic.
Read the story
Junior Engineers and AI: Why Speed With the Tool Says Little About Understanding
Speed with AI tools can rise while understanding falls. A response to Garima Agarwal on testing what junior engineers know without the tool.
Read the story
AI Agent Verification: A Successful Action Is Not a Completed Task
An agent’s tool call can succeed while the incident continues. A response to Sriram Madapusi Vasudevan on writing the completion check into the approval.
Read the story
Error Budgets and AI: Why Healthy Dashboards Can Hide a Comprehension Gap
A service can meet its SLO while its team cannot explain a failed change. A response to Paul LaPosta on comprehension holds.
Read the story
Google Opens Its SynthID AI Detector to the Public
Google's SynthID website now lets anyone check if an image, video, or audio clip was made with AI, a tool Google says handles 1 million checks per day.
Read the story
Meta's New AI Tools Flag Child Exploitation Ad Links
Meta's new AI flags ads that secretly link to child exploitation material hosted elsewhere, building on its removal of 33.2 million such items in H1 2026.
Read the story
OpenAI Agent Breached Australia's Health Website for 3 Months
An OpenAI agent routed around Services Australia's security blocks, wrote to a government database, and went undisclosed for nearly three months.
Read the story
King Charles Told AI's Top CEOs the Risk Is "Existential." Here's What Was Actually Said at Dumfries House.
A royal-convened summit put Nvidia, OpenAI, and Anthropic leadership in one room. What was said, who's warning about what, and what it means for engineering leaders.
Read the story
A UK Council Spent £11,688 on AI-Generated Public Art. Here's What the Bill Actually Covered.
Ten sculptures, no named vendor, and a procurement question every institution adopting AI will eventually face.
Read the story
Comp AI Raises $34M to Expand AI-Powered Security and Compliance Platform
Why monitoring an AI agent is not the same as controlling it — and what $34M of Series A funding says about the next compliance problem.
Read the story
Anthropic and OpenAI Say They'll Embed Independent AI Safety Evaluators
What "embedded" evaluation actually means, what evaluators are asking for, and why skepticism remains high.
Read the storyTopical takes
On AI, agents and security.
Shorter pieces first published on Substack and LinkedIn.
Research briefing
The weekly roundup, without the noise.
One email a week: the handful of stories that actually change a decision, plus the new podcast episode.
Read by 600+ engineering leaders across 40+ countries.